How smart algorithms spot pediatric severe flu before it turns critical
By tracking eight ordinary blood markers, an interpretable machine-learning model accurately predicts which children with flu will develop severe illness.
Reading level
The full story with proper science words explained.
Spotting danger in routine blood tests
A sudden spike in blood sugar seems like an odd clue when dealing with a respiratory infection. Yet in hospitalised children, it was the single strongest warning sign that an infection might turn dangerous. Flu is usually a miserable week of fever and rest, but for some young patients, it leads to hospital care. Doctors need to know early who will recover quickly and who faces life-threatening pediatric severe flu.
To solve this, researchers turned to medical records from 436 young flu patients at Nanjing Children's Hospital. Among them, 114 developed severe illness, and 17.54% of those severe cases proved fatal. The team wanted to know if everyday blood tests could alert doctors before a patient deteriorated.
Filtering the clues
Doctors track dozens of biological numbers, but too much data creates noise. The scientists started with 46 candidate laboratory factors that showed differences in initial tests. They then used LASSO regression, a statistical filter that shrinks irrelevant data down to zero, whittling the list to just eight vital markers.
These eight included blood glucose, liver and kidney markers like AST and BUN, and immune signs like B-cell percentage, CD4+ T cell count, NEUT%, PCT, and complement C3, a protein that flags invaders. Severe cases also had higher rates of bacterial co-infections such as Streptococcus pneumoniae and were less likely to have received an antiviral neuraminidase inhibitor before admission.
Inside the transparent machine
Next, the researchers trained six different computer models on 70% of the patients and tested them on the remaining 30%. A Random Forest model came out on top, achieving an AUROC score of 0.88, beating rivals like Support Vector Machines and simple decision trees. A score of 0.88 means the system was remarkably reliable at distinguishing mild cases from dangerous ones.
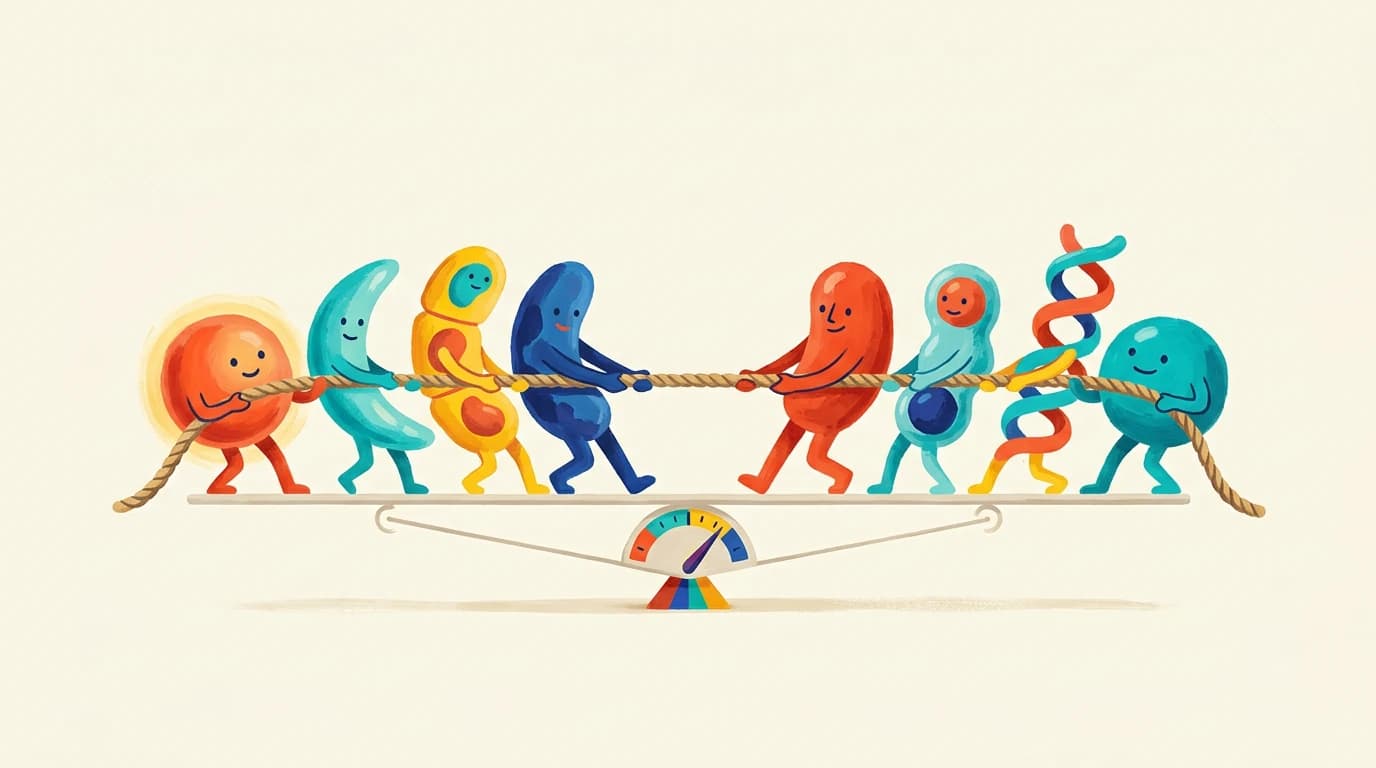
Doctors rarely trust artificial intelligence that acts like a black box with hidden reasoning. To fix this, the team used SHAP, a method adapted from game theory. Think of each blood test as a player in a tug-of-war. One team pulls toward a mild outcome, while the other pulls toward severe illness. SHAP reveals the exact pulling strength of each individual player on the rope.
High blood glucose pulled the hardest toward severe risk, followed by shifts in immune cells. Because doctors could see every tug on the rope, they turned the model into an interactive web tool to assist bed-side choices.
What we still do not know
While the results are promising, limits remain. The study reviewed past records from a single hospital, and patients missing more than a fifth of their data were excluded. Most severe cases involved Influenza A (76.32%), so we do not yet know how well the model handles seasons dominated by Influenza B.
The exact biological reasons why higher B-cell percentages link to worse outcomes also remain unexplained. Scientists still need to test the model prospectively in multi-centre trials before it can guide routine care everywhere.
Science words
- AUROC
- A performance score from 0 to 1 measuring how reliably a test distinguishes between two groups, with higher numbers indicating better accuracy.
- LASSO regression
- A mathematical method that simplifies data models by reducing the impact of unimportant variables to zero.
- SHAP
- A technique borrowed from game theory that calculates the exact contribution of each individual test result toward an algorithm's prediction.
- Neuraminidase inhibitor
- A type of antiviral medication used to treat and slow down flu infections.
- Complement C3
- A protective immune system protein that helps clear out pathogens and direct immune responses.
Check it yourself
This story is based on a real research paper in BMC Medical Informatics and Decision Making by Wu, Qian, Xie et al. We write with AI help and check it against the paper, but the original is the final word.