How computers are learning to read centuries of pressed plants
A review of 24 deep learning studies shows automated software can spot and read old plant labels, but fragmented tools and scarce data hold back progress.
Reading level
The full story with proper science words explained.
Old drawers and messy handwriting
Huge rooms of dried plants sit in museum storage. These sheets hold vital clues about past climate and nature loss. Glued to each sheet is a paper slip. It lists who found the plant, when they found it, and where it grew. Scientists need these facts in online databases to track changes in flowering times over the years. Yet, typing out centuries of strange layouts and messy cursive by hand is painfully slow. Because of this backlog, herbarium label digitization has become an urgent goal for artificial intelligence researchers.
The three-step pipeline
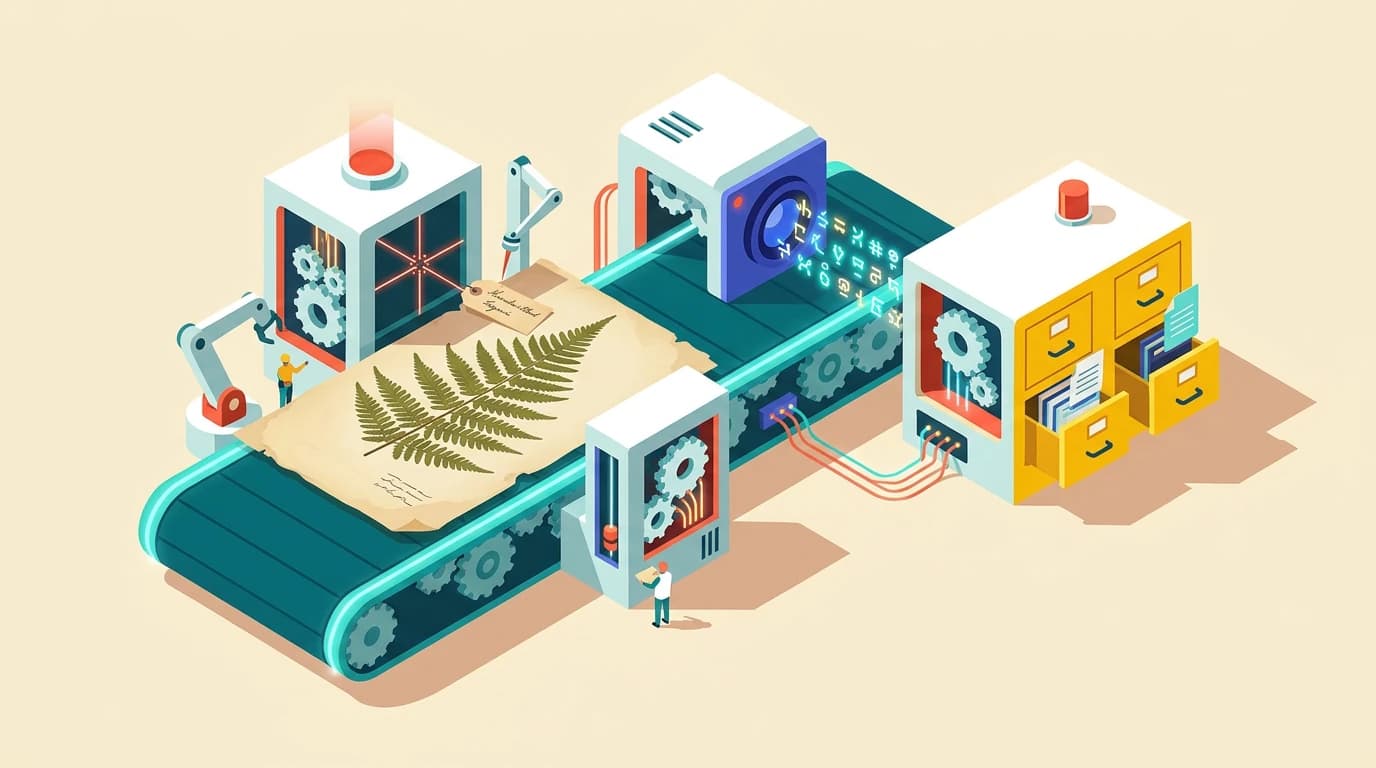
A review looked closely at 24 deep learning studies published from 2018 to 2025. It tested how well computers tackle these old sheets. The job works like an assembly line with three clear steps. First, the computer must find the paper slip among dried leaves and stems. Second, it must read the ink. Third, it must copy the words into a neat, modern database.
If the first step makes a bad crop, the later steps cannot succeed. In machine learning, vision tools like YOLO find the slip on the sheet. Next, optical character recognition systems turn the pictures of letters into plain, editable text. A model called TrOCR uses Vision Transformers to read full lines of tricky handwriting. Finally, language tools sort the raw words into fixed fields. These fields often follow Darwin Core, a global standard for nature records.
Clever guesses and smart shortcuts
The review found that separate tools work very well on their own. One setup named Hespi used a two-step YOLO system. It hit a 97.8% Mean Average Precision score when finding specific parts of a label. Language models can also fix bad text. Combining PaddleOCR with the DeepSeek language model gave a 95.4% score on printed Chinese labels. Smart language models often guess missing words correctly. In fact, raw reading confidence had only a weak link (r = 0.32) to the final output score. Other systems take clever shortcuts. A model called Donut skips the separate reading step completely. It turns label pictures straight into structured files. It scored an 85% median Tree Edit Distance accuracy on labels from the University of Pisa.
Puzzles that remain
Even with these wins, joined-up tools remain rare. Out of the reviewed papers, only Hespi linked all three steps into one tool. In contrast, 13 studies tested only one single step. These systems cannot be compared on scores alone. Each project used unique sheets, custom goals, and separate setups rather than shared test sets. Furthermore, general image datasets have about 100 times more training examples than plant projects. This leaves plant models short of practice data. We still do not know how tiny cropping errors harm final accuracy across big projects. We also do not know how model drift might alter answers over time. Finally, teams must find safe ways to protect locations of rare species under indigenous rules like the CARE principles.
Science words
- Darwin Core
- A standardised set of data fields used internationally to record and share biodiversity information, such as species name, collector, date, and location.
- TrOCR
- An optical character recognition system using Vision Transformers that analyses full lines of text to better interpret difficult handwriting.
- Mean Average Precision (mAP)
- A standard machine-learning score that measures how accurately an object detection model identifies and outlines target regions.
- Tree Edit Distance (TED)
- A metric that calculates how many modifications are needed to transform one nested data structure or text hierarchy into another.
Check it yourself
This story is based on a real research paper in Applications in Plant Sciences by Abbad, Ariouat, Turenne et al. We write with AI help and check it against the paper, but the original is the final word.